主要内容

detectObjects

R2026b

Detect objects in image using Moondream vision-language model (VLM)

Since R2026b

    Description

    Add-On Required: This feature requires the Computer Vision Toolbox Model for Moondream Vision Language Model add-on.

    bboxes = detectObjects(mdModel,I,classNames) detects objects of the specified categories classNames within the image I, using the Moondream™ vision-language model (VLM) mdModel. The function returns the locations of the objects detected in the input image as a set of bounding boxes.

    [bboxes,labels] = detectObjects(mdModel,I,classNames) returns the labels assigned to the bounding boxes. The labels for object classes is an M-by-1 categorical array whose categories are derived from classNames argument.

    detectionResults = detectObjects(mdModel,imds,classNames) detects objects within the images returned by the read function of the input datastore imds.

    [___] = detectObjects(___,roi) detects objects within the rectangular search region roi, in addition to any combination of arguments from previous syntaxes.

    example

    [___] = detectObjects(___,ExecutionEnvironment=executionEnv) specifies the hardware resource on which to run the detector, in addition to any combination of input arguments from previous syntaxes.

    Examples

    collapse all

    Load a pretrained Moondream vision-language model with approximately 1.6 billion parameters into the workspace.

    mdModel = moondream("moondream-1.6B");

    Load an image into the workspace, and display the image.

    I = imread("highway.png");
    imshow(I)
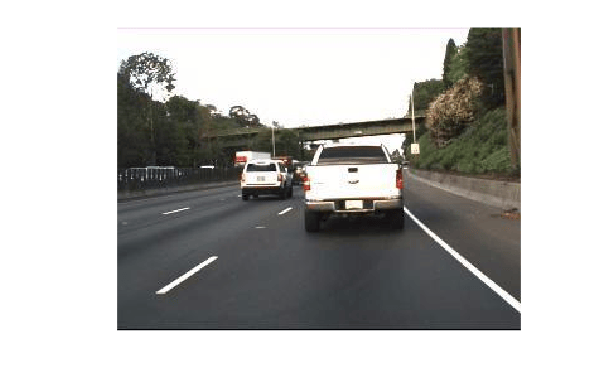
    Figure contains an axes object. The hidden axes object contains an object of type image.

    Define the object categories to detect.

    classes = ["license plate","car"];

    Detect objects of the specified categories in the image using the detectObjects object function.

    [bboxes,labels] = detectObjects(mdModel,I,classes);

    Display the detection results by annotating the image with the detected bounding boxes and labels.

    annotatedImg = insertObjectAnnotation(I,"Rectangle",bboxes,cellstr(labels));
    imshow(annotatedImg)
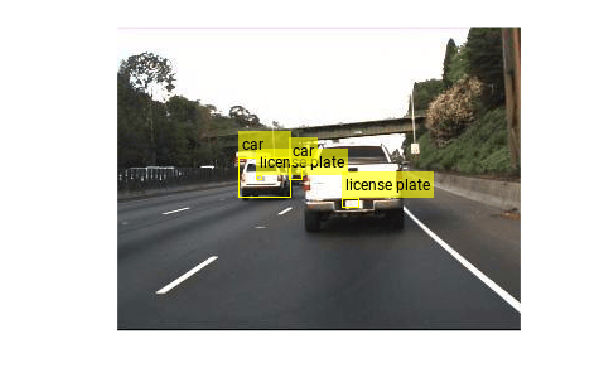
    Figure contains an axes object. The hidden axes object contains an object of type image.

    Input Arguments

    collapse all

    Moondream vision-language model, specified as a moondream object.

    Input image, specified as a numeric array of size H-by-W-by-C. You must specify real, nonsparse, grayscale or RGB images.

    • H— Height of the image.

    • W— Width of the image.

    • C— Number of channels in the image. The channel size of each image must be equal to the input channel size of the network. For example, for grayscale images, C must be 1. For RGB color images, it must be 3.

    Labels of categories to detect, specified as a string scalar, vector of strings, or cell array of character vectors. You can use simple labels, such as "car", or "person" or descriptive phrases such as "yellow school bus", or "person wearing a helmet".

    Data Types: char | string | cell

    Rectangular region of interest, specified as a four-element vector of the form [x y width height] vector. The values of x and y specify the coordinates of the upper-left corner of the region, and [width height] specifies the size of the rectangular region of interest. The region of interest must be fully contained within the input image.

    Datastore of images, specified as any type of datastore that returns image data. When using the read function of the datastore, it must return a table or a cell array with the image data in the first cell.

    Hardware resource on which to run the detector, specified as "auto", "gpu", or "cpu". The table shows the valid hardware resource values.

    Resource Action
    "auto" Use a GPU if it is available. Otherwise, use the CPU.
    "gpu" Use the GPU. To use a GPU, you must have Parallel Computing Toolbox™ and a CUDA® enabled NVIDIA® GPU. Currently, GPU execution is supported for only the pretrained Moondream vision-language model with approximately 1.6 billion parameters. If a suitable GPU is not available, the function returns an error. For information about the supported compute capabilities, see GPU Computing Requirements (Parallel Computing Toolbox).
    "cpu" Use the CPU.

    Output Arguments

    collapse all

    Locations of the detected objects within the input image, returned as an M-by-4 matrix. Each row of the matrix represents the rectangular bounding box for an object in the form [x y w h], where:

    • M is the number of axis-aligned rectangles.

    • x and y specify the location of the upper-left corner of the rectangle.

    • w specifies the width of the rectangle, which is its length along the x-axis.

    • h specifies the height of the rectangle, which is its length along the y-axis.

    Labels for the bounding boxes, returned as an M-by-1 categorical vector containing the names of the object classes, derived from the classNames argument.

    M is the number of bounding boxes detected in the image.

    Detection results from a datastore of images, returned as a two-column table with variable names Boxes and Labels. Each cell of the Boxes column contains an M-by-4 matrix that represents the bounding boxes for the objects found in the corresponding image. Each cell of the Labels column contains an M-by-1 categorical array that represents the corresponding class labels detected in that image.

    Tips

    • The quality of Moondream outputs can vary across different data domains. Validate its predictions using a data set from a domain similar to your intended application.

    Extended Capabilities

    expand all

    GPU Arrays
    Accelerate code by running on a graphics processing unit (GPU) using Parallel Computing Toolbox™.

    Version History

    Introduced in R2026b